Data Engineering Services
Turn data scattered across your business systems into a reliable resource for AI, analytics, and reporting. SysGears is a data engineering service provider aiming to help companies develop data pipelines, integrate disparate systems, build data platforms, and provide ongoing maintenance and support for them. Whether you are starting a new project or addressing limitations in your current data infrastructure, our engineers can design and implement a solution that fits your requirements.
SysGears in Numbers
16+
years of experience in custom software development
350+
corporate customers
110+
software development experts
40+
ongoing projects
Data Engineering Services We Provide

Data Engineering Consulting
Plan a new solution or determine what needs to change in your current environment with our data infrastructure services. SysGears can assess your requirements, available data sources, system architecture, processing needs, and technical constraints to help define an implementation strategy. For existing systems, we can also conduct a technical audit to identify issues with data pipelines, integrations, storage architecture, performance, or reliability and establish priorities for further development.

Data Pipeline Development
Build data pipelines that can handle growing volumes of information without becoming a bottleneck for applications and analytics. Our engineers develop ETL and ELT workflows, implement batch or streaming processing, and configure pipeline scheduling and orchestration based on your data sources, processing requirements, and expected update frequency. We can implement error handling, retries, and monitoring to detect failed or delayed processing jobs and help pipelines recover from disruptions.

Data Integration Development
Connect business applications, databases, and external data sources to improve information availability across your organization. Our developers build integrations using APIs, database connections, or file-based transfers, depending on the capabilities of the systems involved. We can also implement data mapping, format conversions, and synchronization mechanisms in order to handle differences in both data structures and update frequencies.

Data Storage and Warehousing Development
Develop storage solutions tailored to your data types, processing workloads, and analytical needs. SysGears can design and build data warehouses, lakes, lakehouses, and other storage components, selecting architectures and technologies with future growth and maintenance in mind. Our engineers also develop data models, organize storage structures, and configure access mechanisms to support efficient data retrieval and use by downstream applications.

Data Quality Engineering
Improve the accuracy, completeness, and consistency of data across your systems. SysGears can implement data profiling, validation rules, schema checks, and duplicate detection to identify quality issues in incoming and stored information. Our specialists also develop automated testing and monitoring functionality to identify anomalies and unexpected changes in source data. Where needed, we can configure workflows to reject or quarantine records that fail validation before they reach downstream applications.

Data Platform Modernization and Migration
Modernize data infrastructure when outdated components, inefficient processing, or architectural limitations make it difficult to maintain or extend. Our engineers can refactor pipelines, optimize transformations, update storage technologies, and redesign parts of the architecture. We also support migrations between data platforms or infrastructure environments, including data transfer, transformation, validation, and staged cutovers where needed to reduce disruption to ongoing operations.

Data Engineering Maintenance and Support
Keep your data pipelines and platforms functioning as source systems, workloads, and business needs change. SysGears can investigate pipeline failures, resolve integration issues, troubleshoot slow or delayed processing jobs, and update dependencies or configurations. As your requirements evolve, we can adapt existing pipelines to accommodate new data sources or processing needs, running regression tests to verify that our changes do not disrupt established data flows.
Data Engineering for Artificial Intelligence and Machine Learning
AI and ML projects depend on the quality and availability of the information they use. Training datasets need to adequately represent the conditions in which a model is expected to operate, while production models must receive inputs in the expected format and within the required time frame. Discrepancies between training and production data can affect model performance.
SysGears helps companies prepare AI-ready data for model development and deployment. Our engineers can consolidate historical records into structured datasets, implement consistent feature transformations for model training and inference, and build workflows that supply deployed models with updated information. We can also introduce checks for missing values, unexpected schema changes, and inconsistencies in model inputs.
When your project involves data engineering and AI/ML development, SysGears can handle both within a single engagement. Our experts coordinate technical decisions, manage dependencies, and integrate the resulting components into your applications.
Our Data Engineering Capabilities for Complex Technology Ecosystems

Big Data Engineering
Large-scale data processing often calls for distributed computing, especially when workloads become too demanding for a single machine. SysGears works with large datasets, developing distributed data transformations and aggregations. Our engineers also have experience with data partitioning and performance optimization, which become especially important as data volumes increase.
IoT Data Engineering
Connected devices can produce a continuous flow of readings, events, and other operational information. Our IoT development experience includes building software that collects and processes this data, with support for streaming workloads and historical records. The refined data can then be made available to monitoring systems, analytical tools, or applications that need to respond to events from connected devices.
Cloud Data Engineering
SysGears works with AWS, Microsoft Azure, and Google Cloud to develop and maintain data infrastructure. This encompasses configuring storage and processing services and connecting cloud components to databases and applications running elsewhere. Our engineers can also help migrate data workloads to the cloud and review infrastructure configurations when processing performance or operating costs become a concern.
Is your current data infrastructure struggling to keep up with growing workloads or new requirements? Let’s fix that together.
Data Engineering in Practice: Our Projects
Big Data Software for Dental Facilities
The client provides an analytics product for more than 200 dental clinics in the US. Its previous version collected information from dental CRM systems but struggled to handle it efficiently.
Our contribution: SysGears researched the CRM integrations, developed a data model, and rebuilt the system architecture. We also implemented Apache Spark-based processing to return results in the specified format almost immediately after a request.
Our client operates a mobility platform that analyzes data from cameras, sensors, and other IoT devices. They wanted to improve its performance and make the platform easier to customize.
Our contribution: SysGears worked on the microservice architecture, developed pipelines to process large volumes of IoT data, and implemented functionality for third-party integrations, data export, and synchronization.
Movie Theater Subscription Platform
Our client runs a US movie ticketing service that brings together movie information, theater schedules, and showtimes from multiple external providers. Keeping that information flowing through the platform required efficient data processing.
Our contribution: A SysGears Scala engineer refactored and optimized the ETL pipelines handling data from providers such as IMDb and MovieXchange. The work also included event-driven data exchange between backend services using Amazon SNS and SQS.
AI-Powered Home Care Management Software
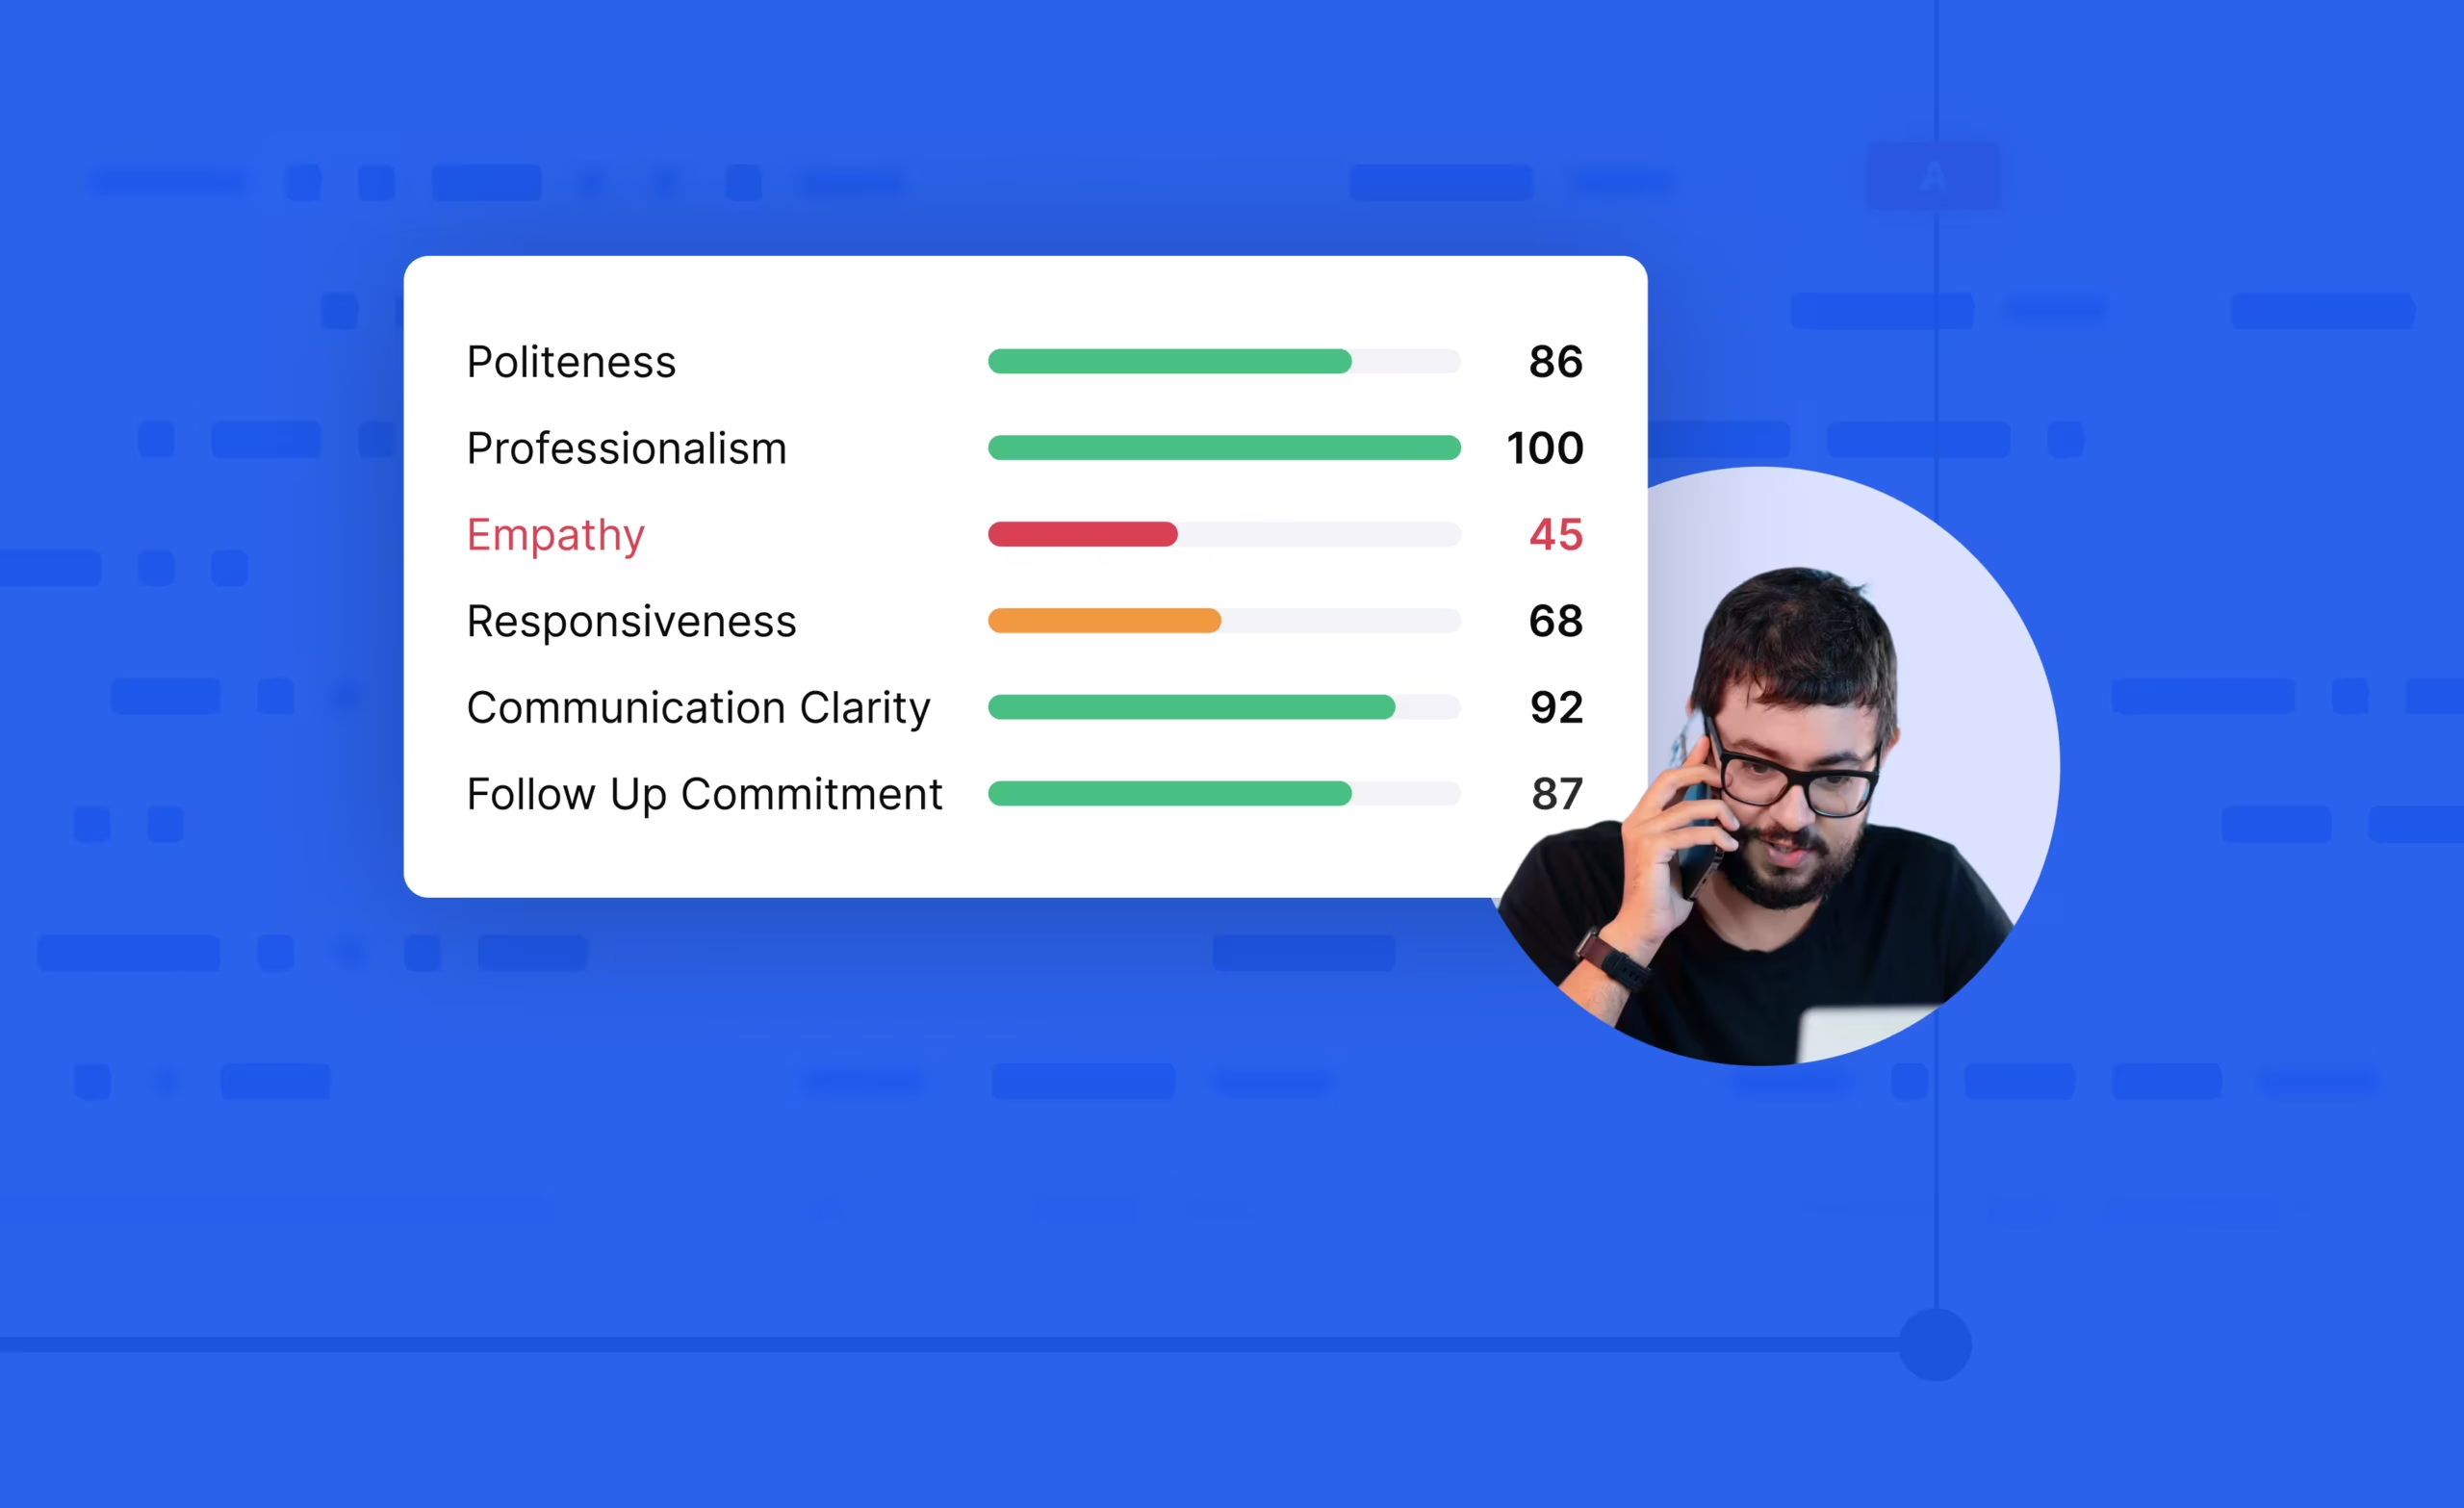
Our client, CommuniCare, helps home care agencies understand employee performance and operational issues by analyzing recorded calls with the help of AI.
Our contribution: SysGears developed call-processing functionality, data storage, and AI analysis capabilities, along with statistical modules for employee performance scoring. The software also transcribes calls, extracts follow-up tasks, and generates agency-level analytics.
Our Clients on Working with SysGears

5.0

“This company has been nothing but transparent and helpful in the development process. They are taking ownership of their code and delivering great quality, while providing a streamlined & open communication channel. I’ve worked with a handful of other vendors in the past and have never gained trust for a company like I have with SysGears.”
Moni Ali
Founder & CEO, Web & App Dev Company
“Before we started working with SysGears, we were concerned that outsourcing our project would be risky and that communication could be difficult. On the contrary, we found that SysGears is competent, flexible, and has a culture of excellent and consistent communication – the perfect ingredients for successful collaboration.”
A.J. Gatlin
Founder, Pecunem GmbH
5.0
“Since the initial engagement, SysGears’ team has been professional and responsive to client needs. They bring a personal touch to the project and have proven to be highly competent.”
Adam Wood
Founder & CEO, CertifiedBy.com
Awards and Recognition


Clutch
Top Scala
Developers

Aciety
Mobile Devices
Development

Upwork
100% Job Success
Aciety
Cloud Computing
Development
Upwork
Top Rated Plus
Aciety
System Architecture
Development
Our Data Engineering Technology Stack
Programming Languages
Scala
Java
Python
JavaScript
TypeScript
Databases
MS SQL
PostgreSQL
MySQL
Cassandra
MongoDB
HBase
Neo4j
Redis
Hadoop
S3
Queues
Kafka
RabbitMQ
SQS
SNS
EventBus
PubSub
Platforms
Apache MESOS
Databricks
Pentaho
AWS & GCP data solutions
ELK stack
Apache Spark
Apache Airflow
Akka
Pekko
Pandas
Modin
Cloud Platforms and Tools
AWS Kinesis
AWS Glue
AWS OpenSearch
AWS S3
AWS RDS
GCP BigQuery
GCP CloudSQL
GCP Pub/Sub
GCP VertexAI
Azure Data Explorer
Azure Databricks
Data Visualization Tools
Kibana
d3js
Why Choose SysGears for Data Engineering Services?

Data Engineering and Big Data Expertise
SysGears, founded in 2010, specializes in data-intensive software development involving complex integrations, architecture modernization, and large-scale processing. For example, our engineering team rebuilt the architecture of an analytics platform serving more than 200 dental clinics in the US and optimized ETL processes for a movie ticketing platform. This kind of experience helps us address the challenges of developing, maintaining, and extending information-dense systems.

Business-Oriented Approach
We aim to develop solutions that meet your business needs without introducing unnecessary complexity. To achieve this, our experts consider your goals, existing systems, data volumes, processing requirements, as well as plans for future development when selecting technologies and designing the architecture. We also weigh the trade-offs between different approaches, including implementation costs, maintenance effort, and scalability.
Data Quality and Reliability
A data pipeline is not particularly useful if the information it delivers is incomplete, inconsistent, or outdated. That is why we account for data validation, transformation accuracy, error handling, and recovery mechanisms during the development process. Our engineers also take into consideration how changes in source data and its growing volumes may affect pipeline reliability.

Security and Data Protection
Different data engineering projects call for different security measures, especially when sensitive business or personal information is involved. We implement role-based access controls, encryption, authentication mechanisms, and audit logging. Our developers also apply secure coding practices, conduct code reviews, and account for applicable data protection regulations when developing integrations, storage components, and processing functionality.
Choose the Right Collaboration Model for Your Data Engineering Project
Full-Scale Development
Entrust your data engineering project to SysGears, from initial planning and architecture design to development, integration, testing, and deployment. Our experts can build a new data platform or modernize your infrastructure, accounting for data sources, processing volume, performance targets, and security requirements. After release, we can also maintain and extend the solution’s functionality as your needs evolve.
Dedicated Team
Get a dedicated team of specialists to handle a specific workstream, such as data pipeline development, system integration, or data platform modernization, or take on a broader scope of data engineering work. Depending on your project, SysGears can provide data engineers, backend developers, QA specialists, and other experts who collaborate as a team throughout the engagement.
Team Augmentation
Add specialists to your engineering team when you need particular expertise or additional development capacity. Our engineers join your established processes and work alongside your internal specialists on tasks such as ETL/ELT development, data warehouse implementation, pipeline optimization, or data migration.
Industries We Work With



How We Deliver Data Engineering Solutions
Discovery and Requirements Analysis
During discovery, we discuss your business goals, current data engineering challenges, and plans for the resulting solution. Our team identifies the requirements for data processing, storage, performance, and security. We also establish project priorities, constraints, and expected deliverables to define what the project will cover and prepare an initial development plan.
Data Source Assessment and Integration Planning
At SysGears, we examine the systems that will supply data to your solution (their available interfaces, data formats, and access restrictions). Our engineers also assess data quality, internal structure, and the availability of historical records to identify potential integration and processing challenges. Based on this information, we determine how to connect the sources. This can be done through APIs, authorized database connections, or file-based transfers.
Data Architecture and Pipeline Design
Our specialists design how data will move between systems, where it should be stored, and how it needs to be processed. This involves planning data pipelines and defining data models, as well as choosing storage and processing technologies that fit the intended workloads. Also, we consider access permissions, security controls, and data quality checks when designing your solution.
Incremental Development and Integration
Our developers build the planned components in iterations, balancing technical dependencies with business priorities. Usually, this involves creating ETL/ELT pipelines, implementing additional processing functionality, configuring storage systems, and connecting source systems with downstream applications. As development progresses, we bring these components together so data can move through the system as planned.
Testing and Data Quality Validation
Our QA specialists work closely with developers throughout the implementation process in order to ensure that pipelines function as expected, integrations work correctly, and the system meets its performance and security requirements. We also check whether records are ingested, transformed, and delivered properly, paying particular attention to missing data, duplicates, and values that do not meet the defined quality rules. Our experts also test how both scheduled and continuously running pipelines respond to errors, retry unsuccessful operations, and recover from failures.
Deployment and Maintenance
At SysGears, we prepare the solution for its target environment and deploy it according to the agreed rollout plan. Where necessary, this stage may also involve migrating existing data, loading historical records, and verifying that pipelines and integrations work correctly after deployment. Once the system is live, SysGears can continue maintaining it by addressing potential issues and adding new data sources, integrations, or processing capabilities as your needs evolve.
How to Start Working with SysGears?
Have a data engineering project in mind? Let’s get it built. Tell us what you are working on through our contact form, on-page chat, or email at info@sysgears.com. You can also book a meeting directly using this link.
You do not need to have every requirement finalized before reaching out. During our first call, we will discuss your project goals, existing data infrastructure, technical challenges, and an engagement model of your preference. If sensitive information needs to be exchanged, we will sign an NDA beforehand. Once we have settled on the scope of work, we will finalize the necessary agreements and begin our cooperation.
For more details on working with SysGears, read this guide.
FAQ
What do data engineering services include?
Data engineering services involve the development and maintenance of systems that collect, process, store, and deliver data intended for operational, analytical, and AI/ML workloads. Depending on your needs, the work may include building data pipelines, integrating multiple data sources, implementing data warehouses and lakes, automating data transformations, and modernizing existing data infrastructure. At SysGears, we develop, test, and deploy the required components and can continue maintaining them after launch.
How much do data engineering services cost?
The cost of such services largely depends on what needs to be built and the state of your current data infrastructure. For example, developing a few pipelines for an existing data warehouse will generally cost less than building a modern data platform with multiple integrations. Data volumes, real-time processing requirements, security measures, and ongoing maintenance also influence the final price.
SysGears charges hourly rates of $35-$80, which vary by specialist role and seniority. Before implementation starts, we review your project needs and technical environment to estimate the work involved and calculate the expected cost.
How long does it take to implement a data engineering solution?
A relatively simple data engineering project, such as building a pipeline between a few well-documented data sources and an existing warehouse, may take several weeks. Larger projects that involve multiple integrations, complex data transformations, or the development of a modern data platform can take several months or longer at our data engineering agency.
SysGears organizes development into iterations, allowing us to implement and test functionality progressively. If needed, we can deliver separate parts of the solution independently, so your team can start using them while we work on the rest. We estimate the timeline based on your existing data infrastructure, data quality, processing requirements, and project scope.
How do you ensure data quality and pipeline reliability?
Ensuring accurate information and reliable data pipelines requires thorough checks at different stages of data processing. In order to maintain data quality, SysGears implements validation rules that identify missing values, duplicate records, inconsistent formats, and values outside permitted ranges.
To improve pipeline reliability, we set up monitoring and alerts to detect failures or processing delays, implement error handling, and introduce retry mechanisms for recoverable failures. Our experts also test pipelines before deployment and can provide ongoing maintenance to address potential issues that can emerge as data sources, volumes, and processing requirements change.
Can SysGears prepare our data for AI and machine learning?
Yes. Our data engineering firm can develop the pipelines that collect information from databases, APIs, application logs, and other relevant sources. Then, we can clean, standardize, and transform it into datasets suitable for model training, evaluation, and inference. We can also prepare historical records for model training. For projects that require continuously updated data, our engineers can automate ingestion and processing, monitor data freshness and quality, and build integrations that supply new records to models running in production.
Why outsource data engineering instead of hiring an in-house team?
Data engineering outsourcing can help you access specialized expertise without having to recruit and onboard additional full-time employees. It can be particularly useful when your internal team lacks experience with specific data platforms, needs extra development capacity, or requires specialized expertise for a short-term initiative that does not justify a permanent hire.
At SysGears, we offer staff augmentation, dedicated teams, and project-based outsourcing. Our specialists can work alongside your internal team or handle a defined scope of data engineering work, depending on your project needs.
Boost your business with custom software
Tell us about your business needs and we’ll suggest a solution
Thank you!
We have received your request and will get back to you within 1 business day.


