


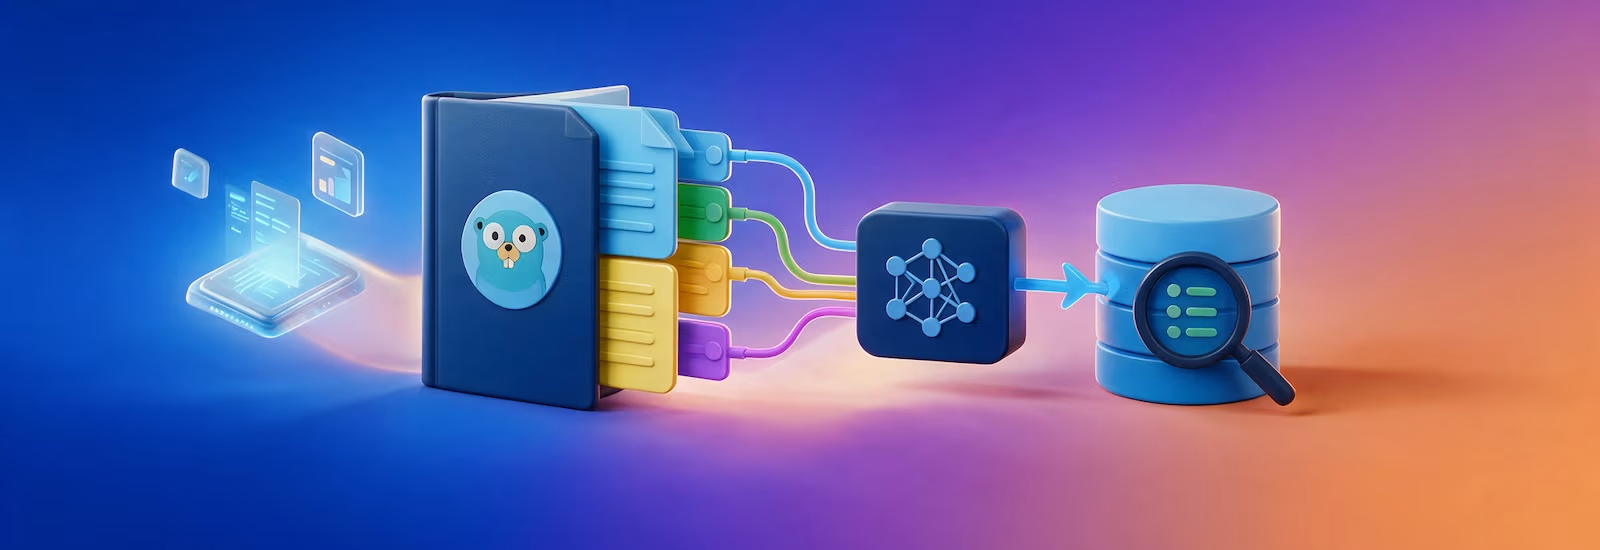
The article explains how chapter-aware chunking can improve retrieval quality in RAG systems that use science and technology books as source material. In particular, it describes the implementation of RAGLibrarian – a custom Go-based page window chunker that combines token and page limits with chapter boundaries to prevent overlap between unrelated sections.
Key Takeaways:
- Fixed token windows work well for texts without clear structural boundaries, but when applied to books, they often produce chunks that cross chapter or topic boundaries.
- Chapter-aware chunking starts a clean chunk when a new chapter or part begins.
- Storing chapter, section, page, and token metadata makes retrieved passages easier to trace, cite, and debug.
- At this point, the chunker doesn’t provide complex document-layout analysis in favour of cheaper processing and better testability.
This article is Part 1 of a three-part series on improving RAG for science and technology books. Continue with Part 2: Vector-Only vs. Hybrid Retrieval for Science and Technology Books and Part 3: Validating LLM Citations in Application Code.
Chunking seems to be one of the most straightforward components to implement in a Retrieval Augmented Generation (RAG) system. Just take the text, create windows, allow some overlap, and feed the snippets to the embedder. For article-like texts, it is good enough.
Not for books.
Technically, do you need anything besides plain fixed overlapping token windows? Fixed windows work well for texts without higher-level structure like chapters, sections, headings, or topic boundaries. When a regular RAG system chunks a book, the retrieval returns a valid passage, which, however, may contain a window crossing the chapter boundary, the final fragment of one topic, or the beginning of the next one. There’s nothing wrong, but the received passage no longer represents a single structural area of the source text. That’s why a book-based RAG system needs additional functionality.
This issue can be solved with RAGLibrarian – a book-chapter-aware page window chunker developed in Go. It produces chunks which should be further used in the embeddings pipeline, maintaining the book structure for future use in Go. The complete project is available on GitHub.
Where Book Structure Disappears During Ingestion
RAGLibrarian ingests books, in particular science and technology books, from PDF and EPUB files. The ingestion service extracts pages, normalises text, creates deterministic chunks, and writes chunk artefacts for the retrieval service to index.
The important part is that ingestion is the last stage where the document stream is present in its original order. If chapter and page context is lost at this point, the retrieval service has to work with anonymous fragments later. That is technically possible, but it is not a good fit for book-based answers. Users want to know where a passage came from, while engineers need enough metadata to debug poor results.
So the default profile is not just “512 tokens with overlap”. It defines a page-aware and chapter-aware compatibility profile:
- record a two-page target for cross-service profile compatibility (the current emission loop does not use this field to choose a window);
- never allow a passage to span more than three source pages;
- cap embedding input at 512 tokens;
- use 120 tokens of overlap, but only within the same structural segment.
The most important part is not the numbers but a boundary rule: an overlap is allowed within one chapter, but not across different chapters or book parts.
Why Fixed Token Windows Were Not Enough
A fixed token window treats a book as a continuous string of text. This approach works well for programming, but it doesn’t account for the book’s structure.
Consider two chapters: the first on programming basics and the second on concurrency. When we use a simple overlapping window, the last paragraph on basics might be included in the first 120 tokens of a chunk from the concurrency chapter. The sequence is fine. Embedding is fine. Nothing breaks.
However, when a user asks a question about concurrency, a reply containing the programming basics information may appear. This is what an invisible bug looks like: it does not show up in any log file; rather, the retrieval results may look off..
There’s also a citation issue. The book-based RAG system is much more helpful when it can identify where a passage came from. If the chunker stores only text and ignores structural context, then the source information will be lost too early.
Thus, the chunker must accomplish two tasks:
- keep the passages small enough for embedding;
- preserve enough structural context for accurate retrieval and citations
We wanted this without relying on an elaborate machine learning model or table of contents construction.
Step 1: Carry a Small Amount of Structure
Chunker retains the current chapter and section during page processing. This state is intentionally simple in Go. It doesn’t rely on PDF, EPUB, SQL, protobuf, or any file type whatsoever.
type StructureContext struct {
	Chapter string
	Section string
}When the chunker sees a chapter heading, it updates Chapter and clears Section. When it sees a section heading, it updates only Section. Every chunk emitted after that gets the current structure.
This is straightforward, but important. In a science and technology book, a chapter can span multiple pages, though its heading appears only once.. And we don’t want the second page to become an “unknown chapter” simply because of that.
Step 2: Identify Only Those Headings We Can Rely On
The heading detector is intentionally conservative: it analyses only the first meaningful line and looks for numbered headings.
var numberedHeading = regexp.MustCompile(
`(?i)^(chapter|part|section)\s+(?:[0-9]+|[ivxlcdm]+|one|two|three|four|five|six|seven|eight|nine|ten)(?:\s*[:.\-]\s*|\s+|$)(.{0,200})$`,
)

func detectHeading(text string) StructureContext {
  for _, line := range strings.Split(text, "\n") {
    line = strings.TrimSpace(line)
    if line == "" {
      continue
    }
    match := numberedHeading.FindStringSubmatch(line)
    if match == nil {
      return StructureContext{}
    }
    if strings.EqualFold(match[1], "chapter") || strings.EqualFold(match[1], "part") {
      return StructureContext{Chapter: line}
    }
    return StructureContext{Section: line}
  }
  return StructureContext{}
}Such a rule would match Chapter 4 Replication and Section 3.1 Consistency Models. Such a rule will not match every book out there, but this is fine at this stage of development.
Here, predictability is preferable to trying something more complicated, which may lead to unexpected errors. Layout detection can be done later on, but the fundamental chunking behaviour must remain deterministic.
Step 3: Combine Page Windows with Token Limits
Token limit still applies in embedding, so the chunker can’t be purely page-based. On the other hand, pages are important for citation; hence, it cannot be purely token-based.
The policy contains the following constraints and versioned target:
type Policy struct {
  MaximumTokens   int
  OverlapTokens   int
  MaximumChunks   int
  TargetPages     int
  MaximumPages    int
  IdentityProfile string
}When pages come in, the chunker stores tokens in a buffer. Each token retains the source page and position in the global list of tokens. Currently, the chunk is emitted when the buffer surpasses the maximum token or maximum page limit. TargetPages is still in the shared profile but isn’t currently used to determine whether the chunk is emitted.
for len(buffer) > policy.MaximumTokens || pageSpan(buffer) > policy.MaximumPages {
  window := chooseWindow(buffer, policy)
  chunk := emit(window, currentStructure)
  chunks = append(chunks, chunk)
  advance := len(window) - policy.OverlapTokens
  buffer = buffer[advance:]
}The result is still a normal sequence of chunks, but every chunk knows where it came from. This small detail pays off later when a retrieval result needs to include source evidence.
Step 4: Flush at Chapter Boundaries
This is the core principle that governs the implementation: overlap is allowed within the current chapter only.
Within a chapter, overlap is an advantage because it preserves continuity between neighbouring chunks. But at a chapter boundary, the same overlap is undesirable since the new chapter should start with a clean context.
The chunker will flush out any pending overlaps whenever it encounters a boundary.
while the current structural segment has buffered tokens:
    - emit the next bounded window
    - advance by window size minus overlap
    - drop a remainder that contains overlap only
clear the previous chapter/section state before accepting the new boundaryThe key point is not the loop itself, but what it prevents: an old overlap is never carried into a new structural segment.
Step 5: Store Metadata That Is Useful Later
Each chunk carries more than the text itself; it carries sufficient metadata to be easily searchable, citable, and traceable.
type Chunk struct {
  ID         string
  BookID     string
  Order      uint64
  Text       string
  Chapter    string
  Section    string
  PageStart  uint32
  PageEnd    uint32
  TokenStart uint64
  TokenEnd   uint64
}The former tells us whether we were able to retrieve a similar paragraph, while the latter allows us to identify exactly where that passage came from – the book, chapter, and a page range. The latter type of retrieval is required for an RAG system working with books.
In addition, the chunk ID is rich with structure and profiling information. This implies that a change in chunking policy would require an update of the indexing version number, not a change to the evidence.
Tests That Safeguard the Behaviour
The tests which protect the code are intentionally kept small. Ingestion tests can help, but their scope is very broad for pinpointing the exact reason behind its breaking upon changing chunking. Unit tests are done on the state machine.
The following test verifies that chapter context is kept across the page boundary:
func TestChunkerCarriesChapterAcrossPages(t *testing.T) {
  chunker := newTestChunker(t, Policy{
    MaximumTokens: 7,
    OverlapTokens: 1,
    TargetPages:   2,
    MaximumPages:  3,
  })
  _, err := chunker.AddPage("book-1", Page{
    Number: 1,
    Text:   "Chapter IV Safe Example\nalpha",
  })
  if err != nil {
    t.Fatal(err)
  }
  _, err = chunker.AddPage("book-1", Page{
    Number: 2,
    Text:   "beta gamma",
  })
  if err != nil {
    t.Fatal(err)
  }
  chunks, err := chunker.Finish("book-1")
  if err != nil {
    t.Fatal(err)
  }
  if len(chunks) != 1 {
    t.Fatalf("chunks = %d, want 1", len(chunks))
  }
  if chunks[0].PageStart() != 1 || chunks[0].PageEnd() != 2 {
    t.Fatalf("pages = %d-%d", chunks[0].PageStart(), chunks[0].PageEnd())
  }
  if chunks[0].Chapter() != "Chapter IV Safe Example" {
    t.Fatalf("chapter = %q", chunks[0].Chapter())
  }
}There is another test that verifies the chapter-boundary rules. Pages one to three fall within the old chapter. Page four is the beginning of a new chapter, and the second chapter has to begin from page four.
func TestChunkerDoesNotCarryOverlapIntoNewChapter(t *testing.T) {
  chunker := newTestChunker(t, Policy{
    MaximumTokens: 100,
    OverlapTokens: 2,
    TargetPages:   2,
    MaximumPages:  3,
  })
  for _, page := range []Page{
    {Number: 1, Text: "one"},
    {Number: 2, Text: "two"},
    {Number: 3, Text: "three"},
    {Number: 4, Text: "Chapter I Start"},
  } {
    if _, err := chunker.AddPage("book-1", page); err != nil {
      t.Fatal(err)
    }
  }
  chunks, err := chunker.Finish("book-1")
  if err != nil {
    t.Fatal(err)
  }
  if len(chunks) != 2 {
    t.Fatalf("chunks = %d, want 2", len(chunks))
  }
  if chunks[0].PageEnd() != 3 {
    t.Fatalf("previous chunk ended on page %d", chunks[0].PageEnd())
  }
  if chunks[1].PageStart() != 4 || chunks[1].Chapter() != "Chapter I Start" {
    t.Fatalf("new chapter chunk = page %d, chapter %q",
      chunks[1].PageStart(),
      chunks[1].Chapter(),
    )
  }
}There are also tests around token bounds for larger overlap windows. While their details go beyond the scope of this article, these tests catch an important class of bugs: non-advancing windows. If a chunker emits a tail that has already been emitted, manifest validation should fail before the bad artefact reaches indexing.
When Fixed Windows Are Enough
Fixed windows are a sufficient default solution for short articles, non-cited plain text, or any system where chapters and section boundaries don’t matter. This solution is simple to understand and use, whereas a good implementation will preserve page/token information.
Chapter-aware fixed windows are needed when there are certain book boundaries that should restrict overlap. A conservative selection of content is another approach and can be applied only if there’s clear evidence that it removes boilerplate and preserves the copyrighted content.
Limitations
The solution doesn’t provide document understanding. It will not reproduce the Table of Contents, categorise prefaces, appendices, or indexes, or infer visual structure from layout in a PDF file.
Structure-preserving extraction is not a reliable source text. While Selection and Chunking are effective for creating evidence, Retrieval and Answer modules must treat all chunks as unreliable input data in further processing.
It is a deliberate choice. This was the point where determinism, testability, and cheapest processing were required. The layout-based processing will definitely benefit the system in the future, but at least the base chunker must not make mistakes chapter by chapter.
Verified Behaviour and Conclusions
Chapter-aware chunking has resulted in cleaner output ingestion for the pipeline without making it a research project.
The key difference is obvious – overlap no longer exists between chapters or parts. Retrieval will receive cleaner passages, responses will provide better source metadata information, and the engineers will receive chunks that are possible to be verified by chapter, page range, order, and token offsets.
This is a good solution for the book-based RAG system that works particularly fine when science and technology books are the source. It does not solve all the document layout problems, but solves the most crucial one in terms of the evidence quality and remains feasible in Go.
Continue to Part 2 of the series.
Visit our blog to read more articles.
If you need a reliable AI development partner, let’s connect.


